Running a 177B Parameter Model Locally on a Single RTX 3090
This demo shows that
Qwen3.8-Flash-Next, a model with roughly 177 billion parameters and a size of 111 GB, can run entirely locally on a single RTX 3090 with 24 GB of VRAM and 128 GB of system RAM.
How Is This Possible?
The key is the
Mixture of Experts (MoE) architecture. Of the 125 billion parameters in the actual backbone, only about 6 billion are activated per token. In addition, the model includes N-gram embedding tables with around 51 billion parameters. These act as lookup memory, are kept in system RAM and are only accessed when needed.
Running
llama.cpp as a service, the required model weights are distributed between system RAM and GPU memory.
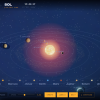
The result shown below was generated in
35 minutes, in a single run, without any manual corrections.
Setup
|
Component
|
Value
|
|
System
|
Linux Mint 22.3
|
|
GPU
|
RTX 3090, 24 GB VRAM
|
|
RAM
|
128 GB DDR4
|
|
Service
|
llama.cpp
|
|
Model
|
Qwen3.8-Flash-Next (MoE)
|
|
Model size
|
111 GB
|
|
Parameters
|
177B
|
|
Quantization
|
Q4_K_M
|
|
Context size
|
128K
|
|
Reasoning
|
On
|
|
Input speed
|
~140 tokens/s
|
|
Output speed
|
~19 tokens/s
|
|
Duration
|
35 min
|
Result
https://www.wartris.com/gfx/solarsystem/
Prompt
Create a 3D model of the solar system with the planets in HTML/JavaScript/CSS. When a planet is selected, the view zooms in and information about the planet is displayed on the right. You can simply have the planets orbit the sun, but don't do any special calculations, just animate them. No timescale calculations, keep it simple, but visually appealing.
Photos
Locally
AI
RTX
3090
Qwen
Views: 17